Ask a language model for a number from one to five and it often bunches around the safe middle. Ask it to explain how likely it is to buy, and the text has more texture—but now you need a consistent way to score the answer.
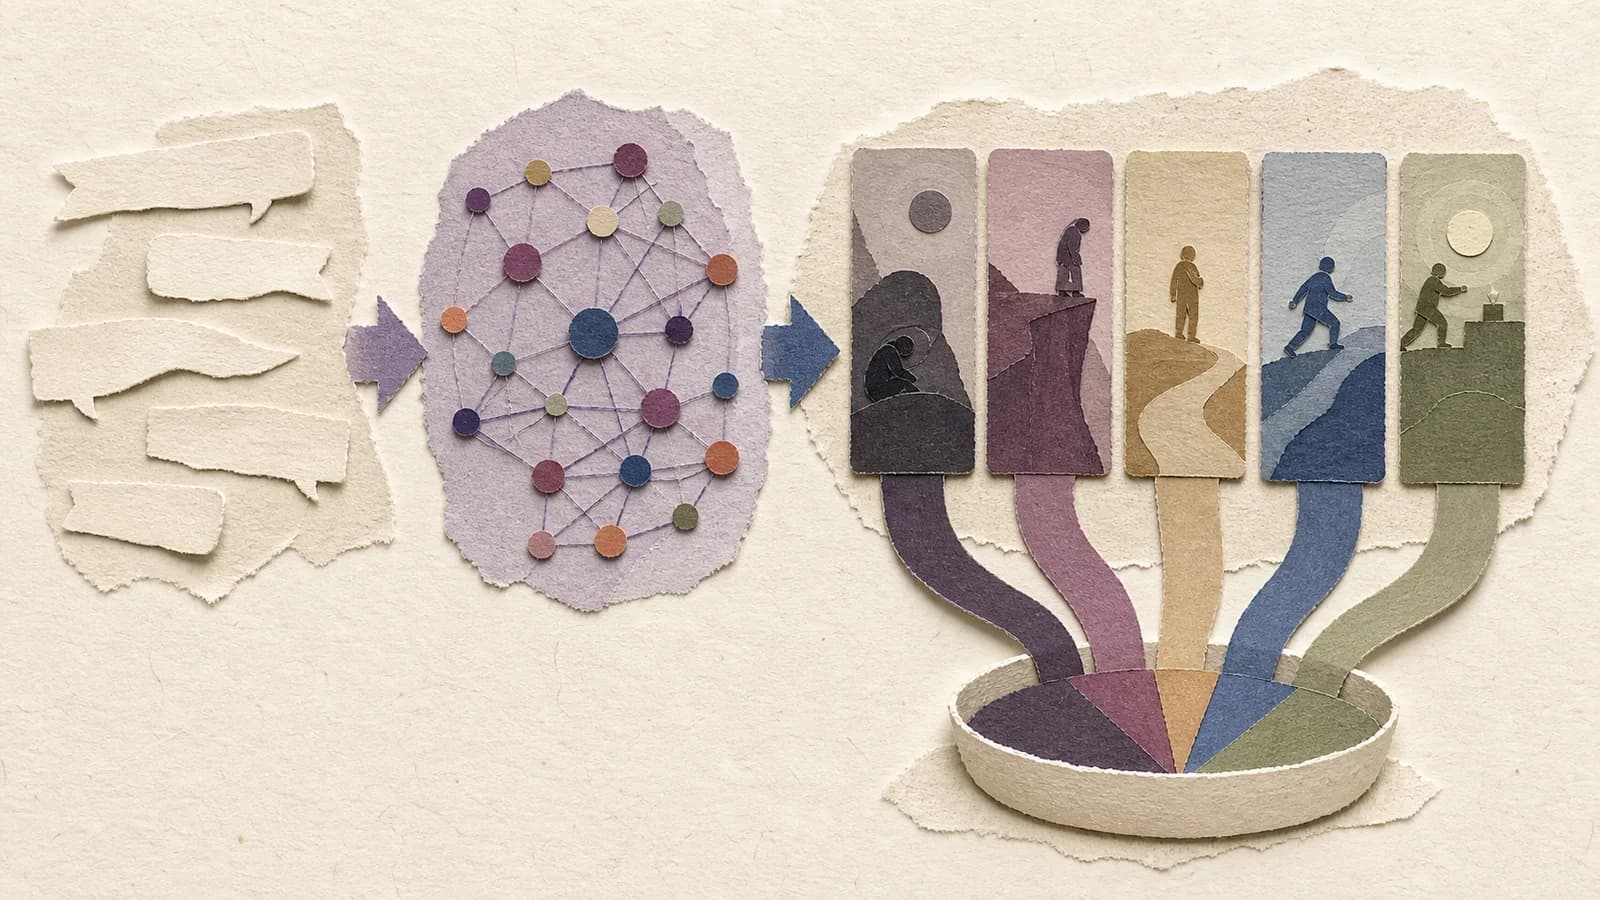
Semantic Similarity Rating, or SSR, handles that translation. It compares the generated response with reference statements for each scale point, then turns those similarities into probabilities. Clever? Yes. Magic? Absolutely not.
The short answer
Key takeaways
- SSR scores natural-language reactions against anchored reference statements instead of asking the model for a bare number.
- The output is a probability distribution across five points, not a certain label.
- Results depend on the model, prompt, embeddings, anchors, scaling, and persona setup. PaperPMF differs from the published preprint in several ways.
Why not just ask for a rating?
Direct numeric prompts can produce cramped, unrealistic distributions. Models know that three looks safely reasonable. Free-text reactions let them express hesitation, conditions, and mixed feelings before any number is assigned.
SSR keeps that richer elicitation step, then applies one scoring rule afterward. The separation is the important idea: generate language first, translate second.
Sources: Maier et al.: LLMs Reproduce Human Purchase Intent via SSR, PyMC Labs: semantic-similarity-rating package
The pipeline in five moves
- Write reference statements for points one through five.
- Generate a free-text purchase-likelihood response.
- Embed the response and each reference statement as vectors.
- Calculate cosine similarity between the response and every anchor.
- Normalize the adjusted similarities into a five-point probability distribution.
A tiny illustrative example
Suppose the response says: “I'd consider it, but $90 feels steep unless the warranty is excellent.” That text may be closest to the middle and slightly positive anchors, with little similarity to “definitely would not buy” or “definitely would buy.”
The result might place most probability on points three and four. That's an illustration, not a calculated PaperPMF output. The actual probabilities depend on the exact anchors, embedding model, and normalization rules.
Sources: PaperPMF methodology
What the preprint found
The SSR preprint reports results across 57 personal-care surveys and 9,300 human responses. In that setup, the method reached 90% of human test-retest reliability and produced distributions with strong shape similarity to human results.
Useful result. Narrow boundary. The paper doesn't show that any random prompt, product category, persona generator, or scoring implementation inherits the same performance.
Sources: Maier et al.: LLMs Reproduce Human Purchase Intent via SSR
How PaperPMF is configured
PaperPMF generates personas with an LLM, asks for two reactions per respondent, uses one generic purchase-likelihood anchor set, and scores with the all-mpnet-base-v2 embedding model. Those are implementation choices, not footnotes.
When auditing a report, check the concept, audience brief, model and prompt versions, reaction count, anchors, embedding model, respondent distributions, and run-to-run stability. A five-point chart without that context is a speedometer with no car attached.
Sources: NIM: Leaving Insight to Digital Twins?, PaperPMF methodology
Sources and verification
Product details are based on official documentation reviewed on August 4, 2026 unless noted. Features and pricing can change; verify them with the provider before making a purchase.
- Maier et al.: LLMs Reproduce Human Purchase Intent via SSR — Underlying preprint and scoped benchmark; reviewed 2026-08-03.
- PyMC Labs: semantic-similarity-rating package — Open-source ResponseRater algorithm and API; reviewed 2026-08-03.
- NIM: Leaving Insight to Digital Twins? — 2026 independent marketing-domain evidence; reviewed 2026-08-03.
- PaperPMF methodology — First-party methodology and configuration differences; reviewed 2026-08-03.